01
Dedicated Bare-Metal Compute
Dedicated GPU infrastructure for AI training, inference, scientific computing and other high-performance workloads requiring predictable resources and direct hardware access.
Global AI compute infrastructure
AI GPU Data Center is developing dedicated, high-density GPU infrastructure for organisations that require bare-metal performance, reserved capacity and greater control over critical compute.
Planned initial architecture: NVIDIA B300 · 1MW first phase · Expansion aligned with demand
Development plan
All figures below describe planned infrastructure. Nothing shown here is operational today.
B300
Planned initial GPU architecture
1MW
Planned first-phase capacity
5MW
Planned phased expansion pathway
Bare Metal
Dedicated client infrastructure
Offtake
Capacity aligned with contracted demand
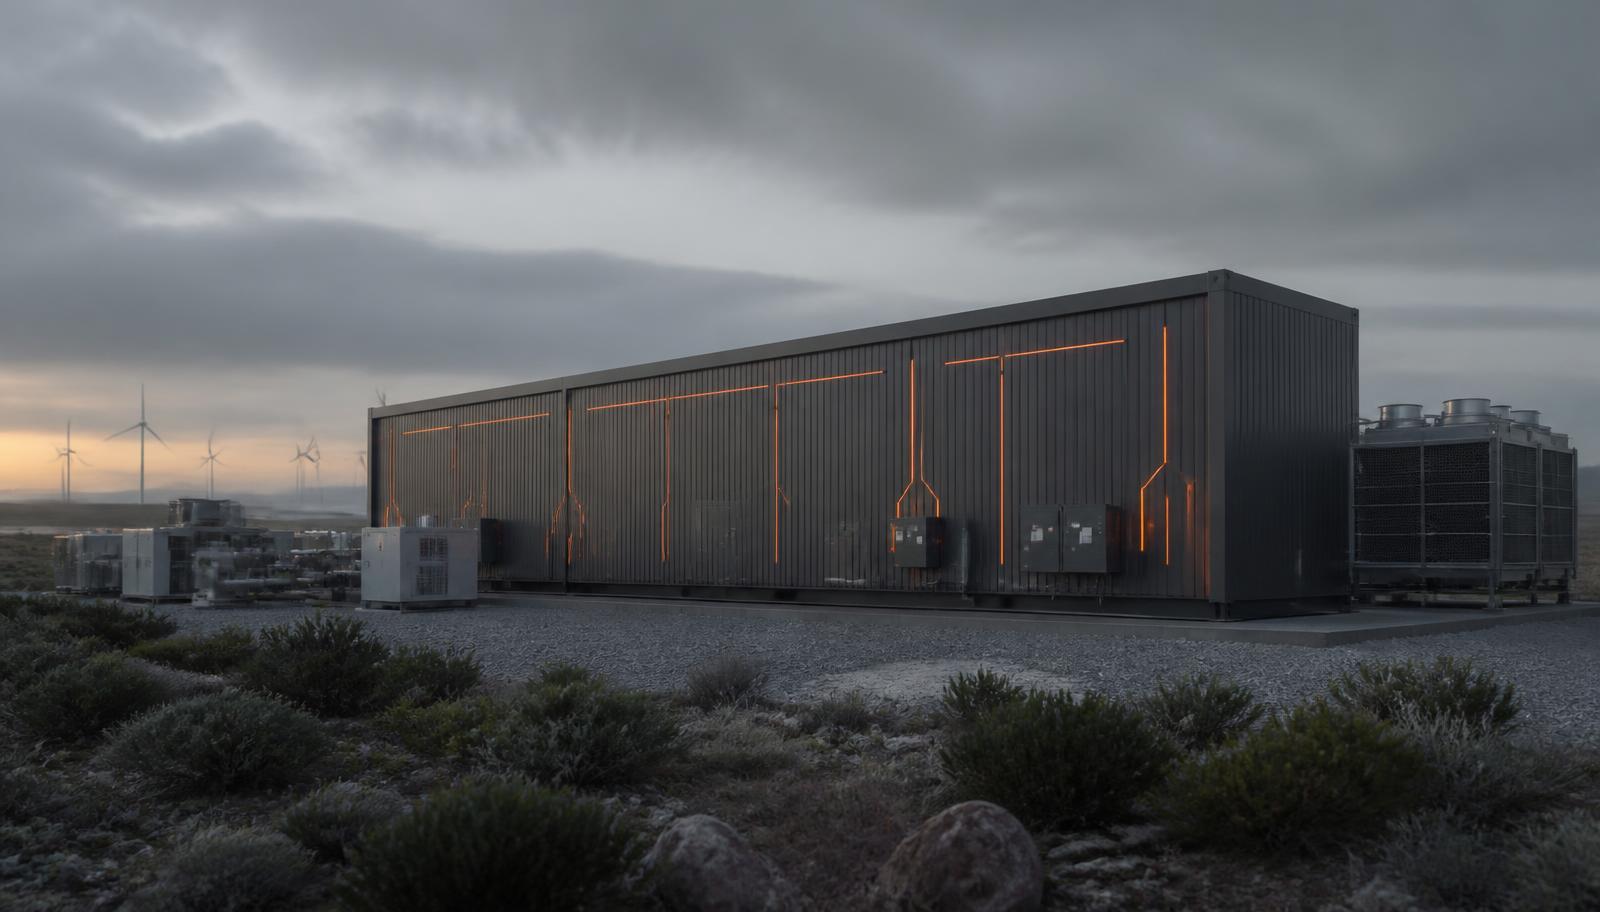
Unit 01
Equipment for the first modular deployment — the unit itself, racks, chillers and cooling — has been ordered, together with eight Supermicro NVIDIA HGX B300 servers carrying 64 B300 GPUs.
Latest development updates
Orders have been placed for the first modular data centre unit, including racks, chillers and cooling, together with eight Supermicro NVIDIA HGX B300 servers carrying 64 B300 GPUs.
The capacity constraint
AI workloads are expanding faster than conventional infrastructure can be planned, financed and deployed. Access to the right hardware is only one part of the constraint. Power, cooling, networking, storage, operations and long-term capacity must function as one integrated system.
AI GPU Data Center is being developed around that full infrastructure requirement.
Supply, distribution, redundancy
Cooling, density, physical security
GPU, CPU, memory
Interconnect, storage, transit
Training, inference, research
One integrated system — a constraint in any layer becomes a constraint on the workload
What we provide
01
Dedicated GPU infrastructure for AI training, inference, scientific computing and other high-performance workloads requiring predictable resources and direct hardware access.
02
GPU, networking, storage and operational configurations designed around the client's workload, scale, security and deployment requirements.
03
Dedicated capacity supported through monitoring, infrastructure operations and lifecycle planning under an agreed service framework.
04
Structured reservations and client offtake agreements align infrastructure expansion with contracted demand and provide a defined pathway to future compute capacity.
From hardware to capacity
AI GPU Data Center's infrastructure model treats compute as an integrated physical and operational system. Hardware selection remains configurable according to workload requirements, with NVIDIA B300 systems forming the planned initial build-out.
Layer 01
High-density accelerated compute forming the core of each deployment. NVIDIA B300 systems are the planned initial architecture; alternative configurations remain available according to client requirements.
Phased development
Phase 01
Dedicated high-density infrastructure based on NVIDIA B300 systems, subject to final engineering and client requirements.
Expansion
Additional capacity developed according to client uptake, power availability, technical requirements and contracted offtake.
Future Scale
A modular operating model designed to support additional capacity and future infrastructure locations as demand develops.
Client offtake
For organisations with substantial future compute requirements, capacity cannot always be procured reactively. AI GPU Data Center works with prospective clients to define workload demand, infrastructure requirements and long-term capacity reservations.
Structured offtake agreements can provide the commercial foundation for phased infrastructure deployment while giving clients a clearer path to dedicated capacity.
Establish workload profile, scale, data characteristics and growth expectations.
Configure GPU, interconnect, storage, power and operational requirements.
Agree reserved capacity, term and the commercial framework for offtake.
Phased deployment against the agreement, with managed infrastructure operations.
Built for consequential workloads
Indicative organisation types only. No listed organisation is a current AI GPU Data Center client.
Why AI GPU Data Center
01
Infrastructure planned around defined client workloads rather than generic shared-cloud availability.
02
Capacity expansion anchored by commercial demand, reservations and client offtake.
03
GPU and supporting infrastructure selected according to technical and commercial requirements.
04
Infrastructure operation remains part of the service rather than becoming an additional client burden.
05
Long-term access to compute treated as an infrastructure decision, not merely an hourly purchase.
Responsible infrastructure
AI GPU Data Center's development framework prioritises efficient infrastructure, demand-aligned expansion, responsible procurement and transparent governance. Environmental and operational commitments will mature alongside the physical infrastructure.
Framework pillars
Speak to AI GPU Data Center about dedicated GPU infrastructure, capacity reservations, client offtake or strategic infrastructure partnerships.
Content on this site describes planned infrastructure. See our infrastructure and capacity disclaimer.